Small Models. Whole Recipe.
OpenCerebral is a non-profit research project training models from scratch and publishing everything about them — weights, quants, token counts, wall-clock times, benchmark tables, and the passes that did not work. Every model through Boris-1.7 was trained on a single consumer GPU, an NVIDIA RTX 3060; Boris-2 is training on a single NVIDIA V100. All are released under the Apache License 2.0 wherever the training data allows it.
The sizes here describe a compute budget, not a ceiling. One GPU at a time is what we have; larger models are intended, and GPU time is the thing standing in the way. If you can contribute compute — credits or an idle card — that is the contribution that moves this furthest. See Get Involved or write to oc@kunix.org.
OpenCerebral is the successor to New Millennium Artificial Intelligence
(NMAI), a division of the
Klondike Software Project. The organization,
the models, and the maintainers are unchanged — only the name is new.
Older references to NMAI, including the previous KSP-NMAI
repository paths, refer to OpenCerebral.
Latest News
2026.10.21: Boris-2-Preview-2 — Open SLM Index 30.58
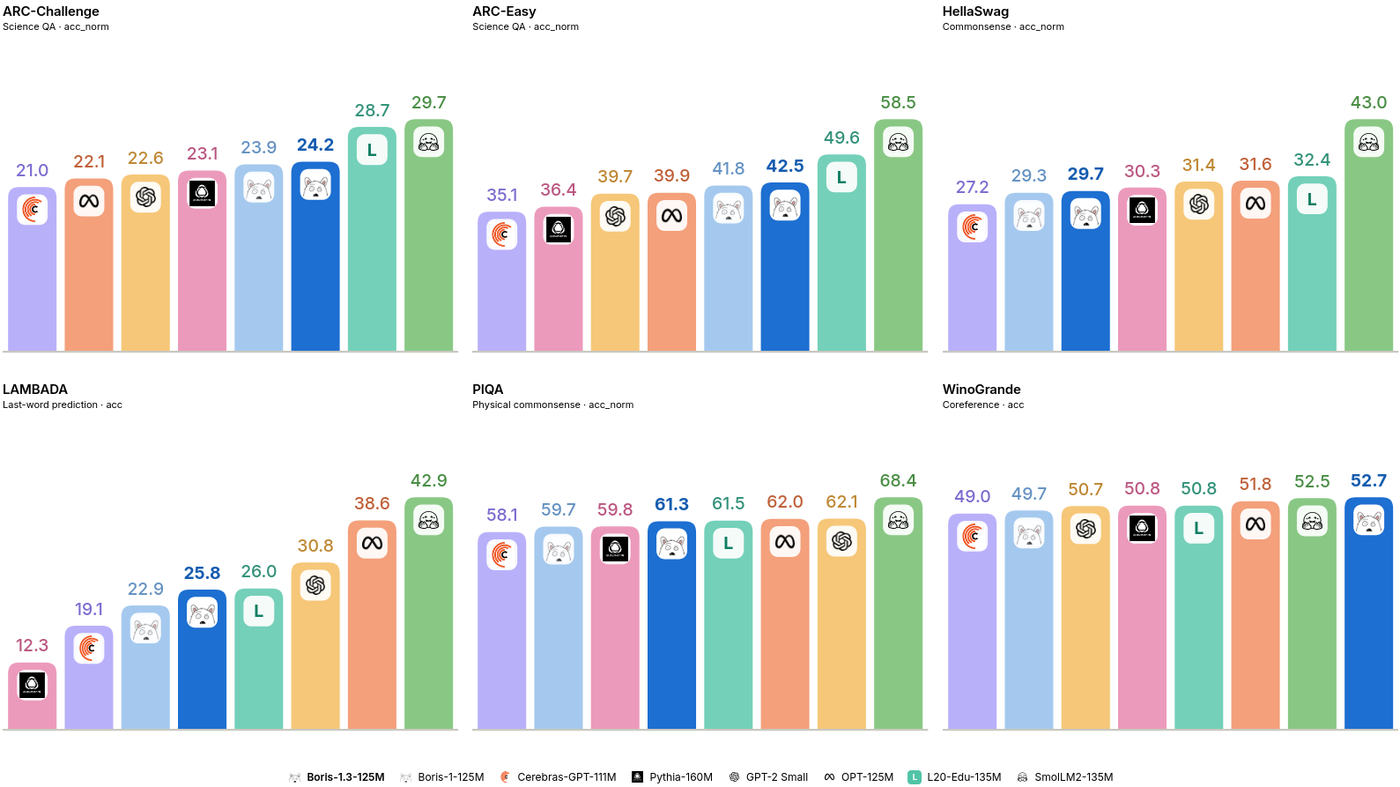
Boris-2's 100B-token checkpoint, with the same short decay as Preview-1. HellaSwag 46.60, ARC-Easy 59.13, PIQA 70.84, and ArithMark-3 up 4.6 points to 42.20 from word-problem data in the decay. The strongest base model we have published. Details on the Boris page.
2026.10.09: Boris-2-Preview-1
The first checkpoint of Boris-2, a 143.7M-parameter model on a new architecture — Canon convolutions, an exact n-gram table descended from Boris-1.7, 2048-token context — trained from scratch on a single V100. After 52.5B tokens it scores 27.91 on the Open SLM Index, ahead of SmolLM2-135M's 27.13 at 2T. The run continues to 200B tokens.
2026.08.31: Boris-1.7-D60M-n30M — does lookup buy what dense weight would?
A 60M-parameter dense trunk with a 30M-parameter n-gram embedding table spliced into the residual stream after block 2, at a fixed 2.5B-token budget. The table is keyed on the literal last 2 and 3 token ids — 468,751 exact rows, no hashing, one gather per position and no matmul, so compute per token barely moves. Ablating the table at inference costs 0.069 bits/char and 0.7–3.1 points across six benchmarks, with both ARC splits moving most. 22h 37m wall clock. Details on the Boris page.
2026.08.12: Lucy-2, text to image from scratch
A 112.5M-parameter rectified-flow diffusion transformer trained from random init at 128×128 — about 44 GPU-hours, against the ~150,000 A100-hours behind Stable Diffusion. It draws scenes, light and material well and fails clearly on counting, relational clauses, and thin geometry. Research-only license, because CelebA is. See Lucy.
2026.08.09: Lucy, unconditional faces
A 71.4M-parameter DDPM generating 128×128 faces, trained from scratch in 9.54 hours with the full training script, the complete 60k-step log, and an EMA preview grid every 3,000 steps published alongside the weights.
2026.08.07: littlerock-1M released
littlerock-1M is a 1,002,720-parameter Llama-architecture model trained from scratch on 5B tokens in 1h 49m.
2026.08.01: Boris-1.3-125M-Instruct and GGUF builds
The instruction-tuned Boris-1.3-125M, finetuned on smol-smoltalk and OASST1 conversational data over 5.6 hours, plus quantized GGUF builds for llama.cpp.
2026.07.31: Boris-1.3-125M — Mean-6 39.38
Seven continued-pretraining passes on top of the Boris-125M base checkpoint, adding ~2.66B tokens (roughly 106% more than the original 2.50B-token run) and lifting the six-benchmark mean from 37.88 to 39.38. Unlike the 75M run, this recipe leads with FineWeb-Edu before DCLM to test whether that ordering avoids the ARC regression. It did. Full pass-by-pass tables on the benchmarks page.
2026.07.26: Boris-1.3-75M
The same continued-pretraining treatment at 75M: three passes, ~3.95B tokens total, Mean-6 of 36.79.
2026.07.15: NMAI becomes OpenCerebral
New Millennium Artificial Intelligence is renamed OpenCerebral, and the first Boris models — Boris-125M and Boris-125M-Instruct — are published on Hugging Face.
Models at a Glance
| Family | What it is | Sizes | License |
|---|---|---|---|
| Boris | Text models, base + instruct + GGUF | 60M, 75M, 125M, 144M, 250M | Apache 2.0 |
| littlerock | Llama architecture; how much fits in a 1M-parameter budget | 1M | Apache 2.0 |
| Lucy | Image diffusion from scratch at 128×128 | 71.4M, 112.5M | Apache 2.0 / research |
Twenty-two models are published in total. See the full model index, or browse the OpenCerebral organization on Hugging Face.